Fireworks AI
Fireworks
★ #85 in AI PlatformsProduct status: Status not recorded
No lifecycle review is recorded for this listing. Its inclusion in the directory does not confirm current availability; check the vendor before relying on it.
No status check date recorded
A fast inference cloud for open models with production-grade reliability, fine-tuning and compositional multi-model deployments. No lifecycle review is recorded for this listing. Its inclusion in the directory does not confirm current availability; check the vendor before relying on it.
Product preview
Overview
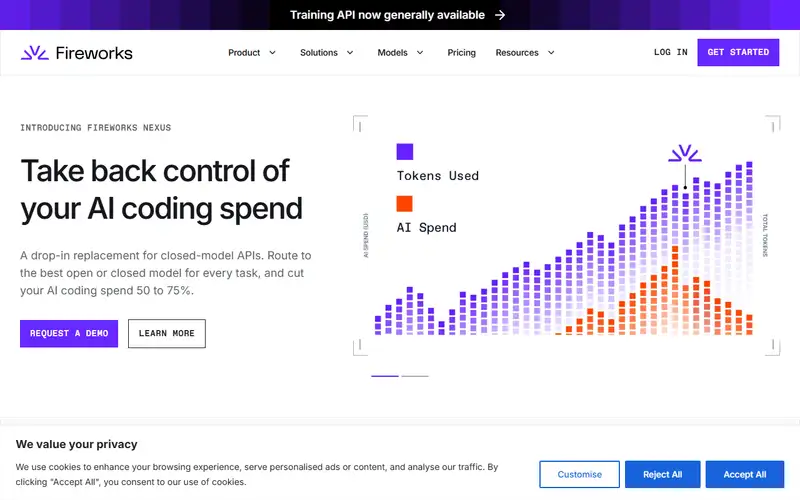
Fireworks AI turns the claim that open weights can also be fast into the product: a serverless catalog with published per-token rates (GLM 5.2 at $1.40 per million input and $4.40 output, Kimi K3 at $3/$15, embeddings from $0.008), and below it a deployment ladder — on-demand dedicated GPUs billed per second at $8.00/hr for H100 and H200, $13.00 for B200, $20.00 for GB300, plus reserved capacity with priority access to newer silicon. Training is the other half: LoRA adapters, full-parameter SFT, DPO and reinforcement fine-tuning priced per GPU hour, driven through a Training SDK and the firectl CLI so dataset to endpoint is scriptable, with Nexus as a routing gateway in front of the cheaper paths.
The honest limit is that what Fireworks opens up is open weights and partner models, not the closed frontier; the pitch is latency and unit economics, which is how the company frames itself. Billing splits three ways — per token, per GPU-second, per training hour — so a job that begins as a token count can end as an always-on dedicated deployment, and a dedicated endpoint costs money whether or not traffic arrives. Pick it for fine-tuned models under real traffic, for streaming products where time-to-first-token decides retention, and for teams about to run vLLM or SGLang themselves. Check the autoscaling floor and idle terms on a dedicated deployment, the quantization behind a quoted price, and how catalog deprecations get announced.
Sources
The factual claims in this review were read from the pages below. Each date is when an editor last opened the source, not when the product changed.
- Vendor site Checked 2026-09-20
- Vendor pricing page Checked 2026-09-20
- Vendor documentation Checked 2026-09-20
Pros / Cons
Pros
- Top-tier serving throughput
- Fine-tuning and LoRA composition
- Production reliability track record
- Broad open-model catalog
Cons
- No proprietary frontier models
- Pricing favors steady workloads
- Smaller ecosystem than hyperscalers
Who it's for
Production deployment of open models
Composed multi-model products
Latency-sensitive applications
Bottom line
Fireworks AI is where open models go when throughput and reliability become product requirements.
Key Features
Tags
Frequently asked questions
Is Fireworks AI currently available?
No lifecycle review is recorded for this listing. Its inclusion in the directory does not confirm current availability; check the vendor before relying on it.
What is Fireworks AI?
Fireworks AI is a AI Platforms tool developed by Fireworks. It was introduced in 2022, and its developer is headquartered in Redwood City, USA. A fast inference cloud for open models with production-grade reliability, fine-tuning and compositional multi-model deployments.
Is Fireworks AI free?
No — Fireworks AI is a paid product. Check the official website for current plans and pricing.
Is Fireworks AI open source?
No — Fireworks AI is proprietary software.
What are the best alternatives to Fireworks AI?
Notable AI Platforms alternatives include Hugging Face, Replicate, Ollama. Browse all 138 tools in our AI Platforms category for a full overview.
Was this listing useful?
Basic Info
- Pricing
- Paid
- Editorial score
- ★ 4.4 / 5 How we score
- Platforms
- WebAPI
- Launched
- 2022
- Headquarters
- Redwood City, USA
- Last verified
- Not recorded