PaddleOCR
Product status: Status not recorded
No lifecycle review is recorded for this listing. Its inclusion in the directory does not confirm current availability; check the vendor before relying on it.
No status check date recorded
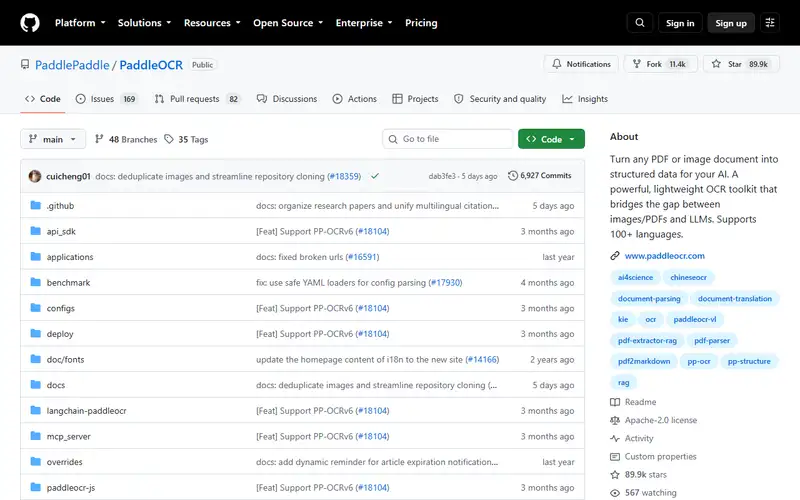
OCR and document-processing toolkit with separate text-recognition, layout/table and vision-language pipelines; model and language support vary. No lifecycle review is recorded for this listing. Its inclusion in the directory does not confirm current availability; check the vendor before relying on it.
Product preview
Decision notes
Official-document research
Based on the cited documentation. We did not use the product, purchase a plan, or run quality, speed or reliability tests in this review.
Consider it for
- Developers choosing models for their own document types
Choose another approach if
- Assuming every model supports every language
- Unreviewed authoritative extraction or free hosted API assumptions
Pricing and conditions
Documented terms
Apache-2.0 permits use without a software license fee; it does not include managed OCR/API usage. CPU/GPU, memory, model downloads, storage, engineering and any cloud services cost separately. No hosted per-page/token rate, seat charge or service quota was confirmed. Currency, regional tax and final infrastructure totals depend on the selected provider; do not interpret local-library access as free hosted processing.
Pricing source read:
Pricing or terms sourceCode, model and service licensing
The repository code is Apache-2.0: retain the license/notices, mark redistributed changes and follow applicable NOTICE/patent conditions; trademarks and warranties are not granted. The examined PP-OCRv5_server_rec model card also declares Apache-2.0, not a blanket license for every downloadable VLM, dependency or third-party weight. Documents, personal data and extracted material need their own rights. A locally installed library does not establish that every wrapper is offline, non-training or zero-retention; hosted APIs have separate service terms.
Basis and limits of the recorded score
Original 4.4/5 retained; no original scoring worksheet or hands-on OCR evidence was available. Documentation is not a measured score.
Overview
PaddleOCR provides text detection/recognition and distinct document-layout, table and vision-language pipelines. Outputs and optional dependencies depend on the pipeline; document workflows can return structured Markdown/JSON. Language coverage is model/version-specific: the examined PP-OCRv5_server_rec card lists Chinese, English and Japanese, while the broader toolkit offers other multilingual models. The current OCR tutorial also lists v6 defaults, so the v5 example is not a latest-model claim. Local deployment needs compatible frameworks, downloaded assets and your own review of scan, layout and number errors.
Sources
The factual claims in this review were read from the pages below. Each date is when an editor last opened the source, not when the product changed.
- Vendor documentation Checked 2026-10-15
- Vendor documentation Checked 2026-10-15
- Vendor documentation Checked 2026-10-15
- Vendor documentation Checked 2026-10-15
Pros / Cons
Pros
- Multiple documented OCR/document pipelines
- Code and an examined model publish explicit licenses
Cons
- Language coverage and dependencies differ by model
- No task accuracy, memory or cloud quote was tested
Who it's for
Reviewable document extraction
Layout/table preparation for retrieval pipelines
Local OCR integration
Bottom line
Select a specific pipeline and weight license, then evaluate it on the documents you must process.
Key Features
Tags
Compare PaddleOCR with alternatives
Frequently asked questions
Is PaddleOCR currently available?
No lifecycle review is recorded for this listing. Its inclusion in the directory does not confirm current availability; check the vendor before relying on it.
What is PaddleOCR?
PaddleOCR is a Agents & Developer Tooling tool developed by PaddlePaddle. OCR and document-processing toolkit with separate text-recognition, layout/table and vision-language pipelines; model and language support vary.
What costs and terms should I check for PaddleOCR?
Apache-2.0 permits use without a software license fee; it does not include managed OCR/API usage. CPU/GPU, memory, model downloads, storage, engineering and any cloud services cost separately. No hosted per-page/token rate, seat charge or service quota was confirmed. Currency, regional tax and final infrastructure totals depend on the selected provider; do not interpret local-library access as free hosted processing.
Is PaddleOCR open source?
The repository code is Apache-2.0: retain the license/notices, mark redistributed changes and follow applicable NOTICE/patent conditions; trademarks and warranties are not granted. The examined PP-OCRv5_server_rec model card also declares Apache-2.0, not a blanket license for every downloadable VLM, dependency or third-party weight. Documents, personal data and extracted material need their own rights. A locally installed library does not establish that every wrapper is offline, non-training or zero-retention; hosted APIs have separate service terms.
What are the best alternatives to PaddleOCR?
Notable Agents & Developer Tooling alternatives include Firecrawl, Browser Use, Daytona. Browse all 33 tools in our Agents & Developer Tooling category for a full overview.
Was this listing useful?
Basic Info
- Pricing
- Free
Apache-2.0 permits use without a software license fee; it does not include managed OCR/API usage. CPU/GPU, memory, model downloads, storage, engineering and any cloud services cost separately. No hosted per-page/token rate, seat charge or service quota was confirmed. Currency, regional tax and final infrastructure totals depend on the selected provider; do not interpret local-library access as free hosted processing.
- Editorial score
- ★ 4.4 / 5 How we score
- Platforms
- LibraryAPICLI
- Last verified
- Not recorded