WhisperX
Product status: Status not recorded
No lifecycle review is recorded for this listing. Its inclusion in the directory does not confirm current availability; check the vendor before relying on it.
No status check date recorded
WhisperX combines Whisper-based transcription, forced alignment for word timestamps and optional speaker diarization in a self-managed pipeline. No lifecycle review is recorded for this listing. Its inclusion in the directory does not confirm current availability; check the vendor before relying on it.
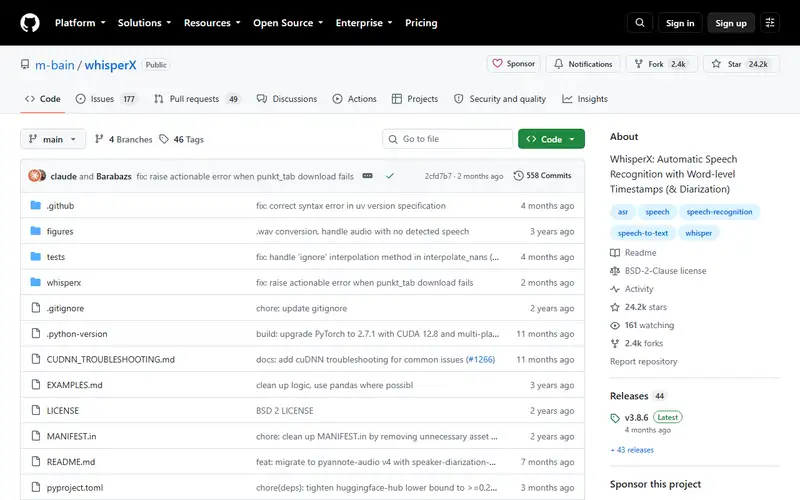
Product preview
Decision notes
Official-document research
Based on the cited documentation. We did not use the product, purchase a plan, or run quality, speed or reliability tests in this review.
Consider it for
- Teams managing ASR and alignment dependencies
Choose another approach if
- Guaranteed speaker identity or perfect overlap handling
- Turnkey deployment without model agreements
Pricing and conditions
Documented terms
The published software license permits use without a license fee; this is self-managed software, not a hosted subscription or included API credits. CPU/GPU, memory, downloads, storage, electricity, engineering and any cloud services cost separately. No vendor per-minute bill was established; currency, tax and regional costs depend on the hardware/cloud/provider you choose.
Pricing source read:
Pricing or terms sourceCode, model and service licensing
WhisperX software is BSD-2-Clause: retain source notices and reproduce notices/disclaimers with binary distributions; no warranty. Whisper weights, alignment models and pyannote have separate licenses. The documented Community-1 model is CC BY 4.0 with attribution and gated access/contact-sharing conditions; its hosted Precision-2 alternative is a different service. A token or model license does not clear recording, speaker or transcript rights. Local execution is not a blanket no-training/no-retention promise for all downloads, wrappers or services.
Basis and limits of the recorded score
Original 4.6/5 retained; original scoring worksheet and hands-on evidence were unavailable. This documentation update does not validate the score.
Overview
WhisperX uses a faster-whisper transcription backend, language-specific alignment models and optional pyannote diarization to produce timed transcripts. Its speaker stage currently documents the gated Community-1 model and Hugging Face access conditions. The README warns that overlapping speech and diarization remain imperfect, and words outside an alignment dictionary may lack timestamps. CPU and GPU paths differ, with version-specific CUDA/dependency requirements. This is an integrated pipeline to configure and review, not evidence that transcription or speaker attribution is solved in one pass.
Sources
The factual claims in this review were read from the pages below. Each date is when an editor last opened the source, not when the product changed.
- Vendor documentation Checked 2026-10-15
- Vendor documentation Checked 2026-10-15
- Vendor documentation Checked 2026-10-15
Pros / Cons
Pros
- Transcription, alignment and speaker stages are explicit
- Configurable local processing pipeline
Cons
- Alignment depends on language-specific models
- Overlap, missing timestamps and speaker errors need review
- Extra model licenses and access conditions
Who it's for
Subtitle alignment drafts
Speaker-labelled interview transcripts
Audio corpus preparation with review
Bottom line
Consider WhisperX for reviewable timed transcripts when you can manage each model, dependency and access condition.
Key Features
Tags
Compare WhisperX with alternatives
Frequently asked questions
Is WhisperX currently available?
No lifecycle review is recorded for this listing. Its inclusion in the directory does not confirm current availability; check the vendor before relying on it.
What is WhisperX?
WhisperX is a Audio Generation tool developed by WhisperX community. WhisperX combines Whisper-based transcription, forced alignment for word timestamps and optional speaker diarization in a self-managed pipeline.
What costs and terms should I check for WhisperX?
The published software license permits use without a license fee; this is self-managed software, not a hosted subscription or included API credits. CPU/GPU, memory, downloads, storage, electricity, engineering and any cloud services cost separately. No vendor per-minute bill was established; currency, tax and regional costs depend on the hardware/cloud/provider you choose.
Is WhisperX open source?
WhisperX software is BSD-2-Clause: retain source notices and reproduce notices/disclaimers with binary distributions; no warranty. Whisper weights, alignment models and pyannote have separate licenses. The documented Community-1 model is CC BY 4.0 with attribution and gated access/contact-sharing conditions; its hosted Precision-2 alternative is a different service. A token or model license does not clear recording, speaker or transcript rights. Local execution is not a blanket no-training/no-retention promise for all downloads, wrappers or services.
What are the best alternatives to WhisperX?
Notable Audio Generation alternatives include ElevenLabs, Suno, Udio. Browse all 51 tools in our Audio Generation category for a full overview.
Was this listing useful?
Basic Info
- Pricing
- Free
The published software license permits use without a license fee; this is self-managed software, not a hosted subscription or included API credits. CPU/GPU, memory, downloads, storage, electricity, engineering and any cloud services cost separately. No vendor per-minute bill was established; currency, tax and regional costs depend on the hardware/cloud/provider you choose.
- Editorial score
- ★ 4.6 / 5 How we score
- Platforms
- LibraryPython
- Last verified
- Not recorded