Triton Inference Server
Product status: Status not recorded
No lifecycle review is recorded for this listing. Its inclusion in the directory does not confirm current availability; check the vendor before relying on it.
No status check date recorded
NVIDIA's inference workhorse: squeeze every GPU with batching and multi-model serving. No lifecycle review is recorded for this listing. Its inclusion in the directory does not confirm current availability; check the vendor before relying on it.
Product preview
Overview
Triton is NVIDIA's inference server: one process that serves models from several different runtime backends, exposes them over HTTP and gRPC as well as through interfaces that OpenAI and KServe clients already speak, and reports metrics so a deployment can be watched. The documentation's quick-start list spans TensorRT-LLM, vLLM, Python with Hugging Face models, PyTorch, ONNX and OpenVINO, and its feature list includes the tricks large language models need — constrained decoding, function calling and speculative decoding. It is the boring, dependable layer an enterprise points its whole model estate at.
It suits teams consolidating many models, especially vision, speech and embedding workloads, onto shared graphics cards and needing to prove utilisation and health with numbers. It suits less well anyone whose priority is the shortest path from a notebook to a running endpoint: describing a model to this server means laying out a model repository in the required shape and writing configuration before the first request works, which is a real cost even though a quick-deployment guide exists for each backend. It also suits less well pure language-model serving, where the specialised engines are the ones that move fastest.
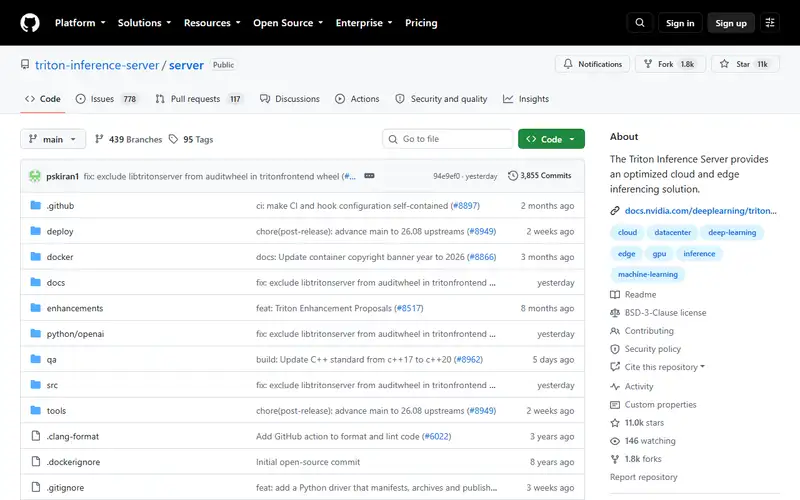
Not verified: no server was installed and no model was loaded, so batching behaviour, the multi-backend claim and the metric output were not observed. The backend and feature lists come from the vendor's documentation pages. The repository interface reported about 11,069 stars, 1,853 forks, the BSD 3-Clause licence and a push on 10 October 2026, so the project was active on the day this was written; its release notes and its compatibility matrix were not read, so which versions pair with which library versions is unchecked. Note that the name is also used by an unrelated compiler project, and that other project was not examined here.
No content sources are recorded for this entry. Its inclusion and existing score do not establish that its claims have been independently verified.
Pros / Cons
Pros
- Squeezes GPUs batching can reach
- One server, many frameworks
- Prometheus metrics native
- NVIDIA-tested on NVIDIA silicon
Cons
- Config pyramids before first request
- LLM serving cedes ground to vLLM/SGLang
- Model repository discipline required
Who it's for
High-throughput vision and speech serving
Multi-model GPU consolidation
Enterprise inference with metrics
Batch scoring farms
Bottom line
NVIDIA's multi-backend model server — the consolidation layer for mixed vision, speech and language estates, and configuration work before the first request goes through.
Key Features
Tags
Frequently asked questions
Is Triton Inference Server currently available?
No lifecycle review is recorded for this listing. Its inclusion in the directory does not confirm current availability; check the vendor before relying on it.
What is Triton Inference Server?
Triton Inference Server is a AI Platforms tool developed by NVIDIA. It was introduced in 2018, and its developer is headquartered in Santa Clara, USA. NVIDIA's inference workhorse: squeeze every GPU with batching and multi-model serving.
Is Triton Inference Server free?
Yes — Triton Inference Server is free to use.
Is Triton Inference Server open source?
Yes — Triton Inference Server is open source. The source code is publicly available at https://github.com/triton-inference-server/server.
What are the best alternatives to Triton Inference Server?
Notable AI Platforms alternatives include Hugging Face, Replicate, Ollama. Browse all 138 tools in our AI Platforms category for a full overview.
Was this listing useful?
Basic Info
- Pricing
- Free
- Editorial score
- ★ 4.5 / 5 How we score
- Platforms
- ServerDockerKubernetes
- Launched
- 2018
- Headquarters
- Santa Clara, USA
- Last verified
- Not recorded